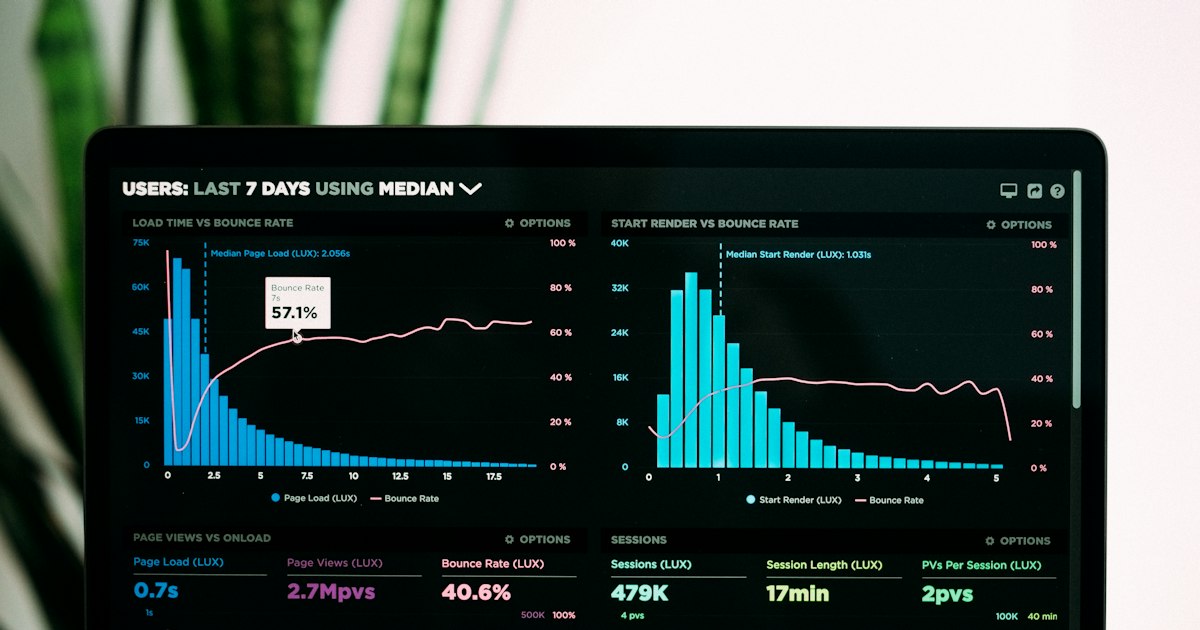
OpenTelemetry won the observability standards war: vendors, clouds and frameworks now emit OTel natively, and new instrumentation is increasingly written against its APIs first. For teams, that settles the strategic question — the remaining work is tactical adoption without drowning in signal volume.
Traces first, then metrics
The highest-value starting point is distributed tracing across service boundaries, because cross-service latency is the hardest problem to diagnose without it. Add spans to your HTTP and queue clients, propagate context, and you will surface bottlenecks that metrics alone never showed.
Instrument once, export anywhere
The point of OpenTelemetry is decoupling instrumentation from the backend. Choose an open vendor-neutral pipeline so that switching or duplicating backends later is a configuration change rather than a re-instrumentation project.
Control the volume
Full-fidelity telemetry gets expensive fast. Sample deliberately, drop low-value attributes, and set cardinality limits on labels before a single high-cardinality tag inflates your bill. Governance at the collector is far cheaper than pruning later.
Instrumenting without boiling the ocean
Start with the three signals that answer production questions — request latency, errors and saturation — via auto-instrumentation for your framework, then add spans only where a specific debugging question needs them. The failure mode is instrumenting every function and paying for spans nobody queries; each new instrumentation should be justified by a question someone actually asked during an incident. Traces across service boundaries matter far more than depth within one service.
The cardinality and cost conversation
OTel makes it easy to attach high-cardinality attributes to metrics, and cardinality is where observability bills explode. Establish attribute conventions centrally — bounded enums for status and route, IDs only on traces and logs — and enforce them in shared libraries so every service agrees. Sampling belongs in the pipeline rather than the application: tail sampling keeps all errors and slow traces while dropping the routine middle.
Key takeaways
- Auto-instrument first; add custom spans only to answer real questions.
- Bound metric attributes centrally — cardinality drives the bill.
- Tail-sample in the pipeline: keep errors and slow traces, drop the routine.
Final thoughts
OpenTelemetry standardization means instrumentation investment finally compounds across vendors and years, and the teams treating attribute conventions as shared infrastructure are the ones whose observability stays affordable at scale.